Paper summary: Kandinsky: an Improved Text-to-Image Synthesis with Image Prior and Latent Diffusion
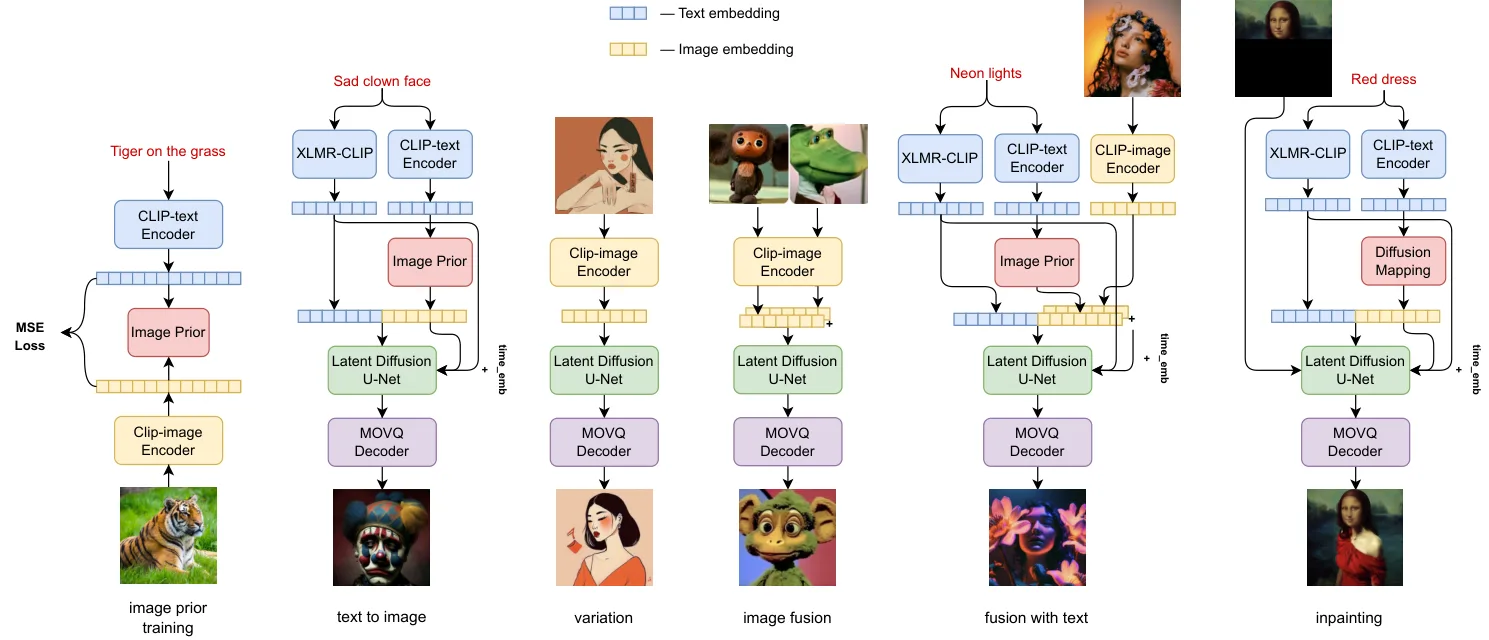
Kandinsky combines a separately trained image prior, which maps CLIP text embeddings to CLIP image embeddings, with latent diffusion and a modified MoVQ autoencoder: 3.3B parameters, open weights.
Problem
Diffusion models generate images either directly in pixel space or in a compressed latent space. The question here is how to combine the strengths of an “image prior” design (as in DALL·E 2) with efficient latent diffusion, and release it openly.
Method
The Kandinsky model described in the paper has three parts:
- An image prior, trained separately, that maps a CLIP text embedding to a CLIP image embedding.
- A latent diffusion model that generates image latents conditioned on that embedding.
- A modified MoVQ autoencoder that decodes latents to pixels.
The whole system has 3.3B parameters. A demo supports text-to-image, image fusion, variations, and text-guided inpainting and outpainting. Code and checkpoints are released.
Key results
The paper reports an FID of 8.03 on COCO-30K, which the authors describe as the top measured result among open-source models at that time.
Limitations
From the authors’ own section: the images look natural, but semantic coherence between text and image can be improved, as can absolute FID and human-judged image quality.
#genai#diffusion#text-to-image
Sources
- Kandinsky: an Improved Text-to-Image Synthesis with Image Prior and Latent Diffusion (arXiv:2310.03502) — arXiv
- Hugging Face Daily Papers, 2023-10-06 — Hugging Face
- Kandinsky: an Improved Text-to-Image Synthesis with Image Prior and Latent Diffusion (arXiv HTML full text) — arXiv
- Code repository (linked in the paper) — GitHub
This is a summary written from the linked public sources. Figures and numbers are as reported there.