Paper summary: Florence-2: Advancing a Unified Representation for a Variety of Vision Tasks
Florence-2 is a single sequence-to-sequence vision model that takes a text prompt as the task instruction and answers in text, covering captioning, detection, grounding and segmentation, trained on 5.4B annotations.
Problem
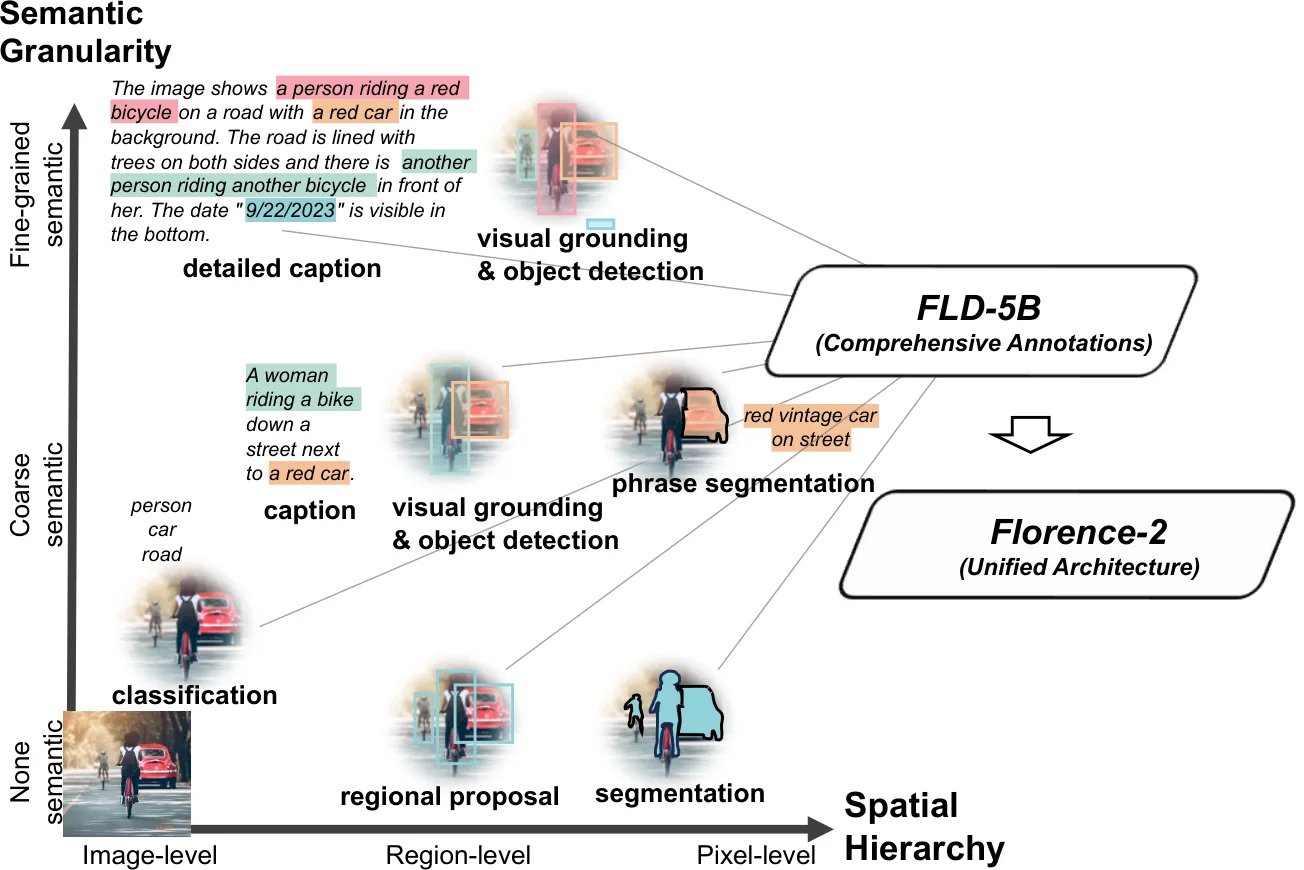
Big vision models transfer well, but they usually need a separate head or model per task. They can’t simply be told what to do. Handling everything from image-level captions to pixel-level regions needs both spatial hierarchy and semantic granularity.
Method
Florence-2 uses a sequence-to-sequence design: an image plus a text prompt describing the task goes in, and the answer comes out as text. For tasks like detection, grounding or segmentation, locations are written as tokens.
Training such a multi-task model needs a lot of consistent annotation. The authors built FLD-5B, about 5.4 billion annotations on 126 million images, with a data engine that alternates automatic annotation and model refinement.
Key results
The paper reports Florence-2 as a strong vision foundation model, with what the authors call unprecedented zero-shot and fine-tuning ability across numerous tasks.
Limitations
The extracted text doesn’t include a dedicated limitations section. Much of the annotation is generated automatically by the data engine, so dataset quality depends on that pipeline.
#cv#vision-language#foundation-models
Sources
- Florence-2: Advancing a Unified Representation for a Variety of Vision Tasks (arXiv:2311.06242) — arXiv
- Hugging Face Daily Papers, 2023-11-13 — Hugging Face
- Florence-2: Advancing a Unified Representation for a Variety of Vision Tasks (arXiv HTML full text) — arXiv
This is a summary written from the linked public sources. Figures and numbers are as reported there.