Paper summary: SOLAR 10.7B: Scaling Large Language Models with Simple yet Effective Depth Up-Scaling
SOLAR 10.7B grows a smaller LLM by duplicating its layer stack, trimming the overlap and continuing pre-training ("depth up-scaling"), a simpler route than mixture-of-experts.
Problem
Scaling a model up usually means training a bigger one from scratch. Mixture-of-experts up-scaling reuses weights but complicates training and inference. Is there a simpler way?
Method
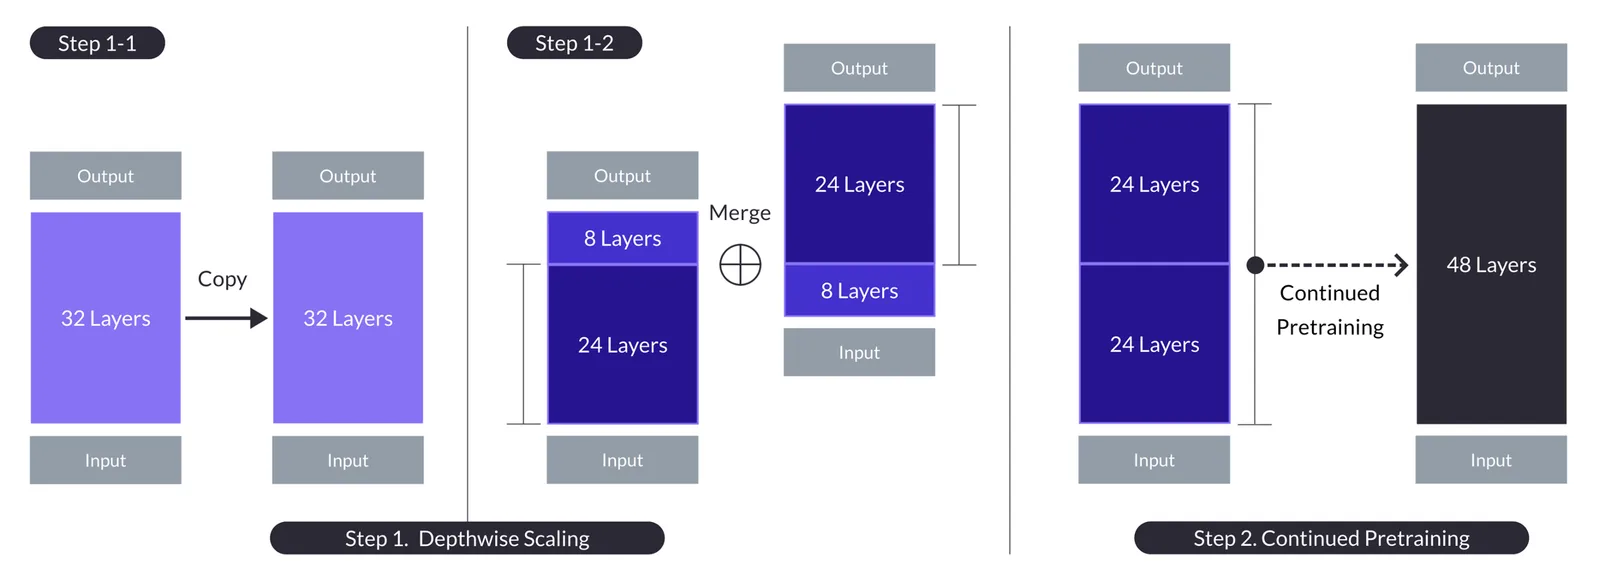
Depth up-scaling (DUS), shown in the paper’s Figure 1, works in two stages:
- Depthwise scaling: take the base model, make a copy, remove some layers from the end of one copy and the start of the other, and stack them into one deeper network.
- Continued pre-training, to recover and improve the performance that drops right after stacking.
No new architecture components are needed.
Key results
The authors present SOLAR 10.7B, which shows strong performance across NLP tasks, and SOLAR 10.7B-Instruct, which they report surpasses Mixtral-8x7B-Instruct. Both are released under Apache 2.0.
Limitations
From the paper:
- the number of removed layers was chosen mainly because of hardware limits, not shown to be optimal
- continued pre-training is costly, so hyperparameters weren’t explored thoroughly
- training and inference demands may limit who can use the model
- like other models, it can reflect biases in its training data
Sources
- SOLAR 10.7B: Scaling Large Language Models with Simple yet Effective Depth Up-Scaling (arXiv:2312.15166) — arXiv
- Hugging Face Daily Papers, 2023-12-27 — Hugging Face
- SOLAR 10.7B: Scaling Large Language Models with Simple yet Effective Depth Up-Scaling (arXiv HTML full text) — arXiv
This is a summary written from the linked public sources. Figures and numbers are as reported there.