Paper summary: DocLLM: A layout-aware generative language model for multimodal document understanding
DocLLM adds layout awareness to an LLM using only text bounding boxes, with no image encoder, via disentangled text/layout attention and a text-infilling pre-training objective.
Problem
Enterprise documents (forms, receipts, contracts) carry meaning in both their text and their layout: a number means something different in the “Total” box than in the address. Many multimodal LLMs handle this with expensive image encoders.
Method
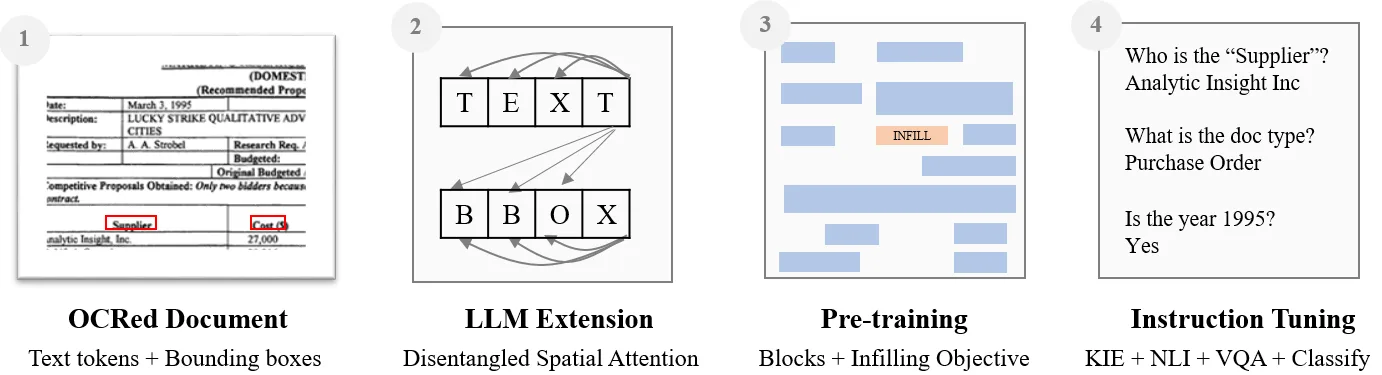
DocLLM is a lightweight extension of a standard LLM:
- Each text token comes with its bounding box. There’s no image encoder.
- Attention is decomposed into disentangled matrices that capture text–text, text–layout and layout–layout interactions.
- Pre-training uses a text-infilling objective, predicting missing text segments, which suits irregular layouts better than strict left-to-right prediction.
- The model is then instruction-tuned on a large dataset covering four core document-intelligence tasks.
Key results
The abstract reports that DocLLM outperforms state-of-the-art LLMs on 14 of 16 datasets across those tasks, and generalises to 4 of 5 previously unseen datasets.
Limitations
The extracted text has no dedicated limitations section. Because it relies only on text and boxes, DocLLM needs OCR or born-digital text with coordinates as input; purely visual elements without text aren’t represented.
Sources
- DocLLM: A layout-aware generative language model for multimodal document understanding (arXiv:2401.00908) — arXiv
- Hugging Face Daily Papers, 2024-01-02 — Hugging Face
- DocLLM: A layout-aware generative language model for multimodal document understanding (arXiv HTML full text) — arXiv
This is a summary written from the linked public sources. Figures and numbers are as reported there.