Paper summary: CLEAR: Character Unlearning in Textual and Visual Modalities
CLEAR is an open benchmark for removing information about specific people from multimodal models, with 200 fictitious individuals, 3,700 images and linked Q&A, used to compare 11 unlearning methods.
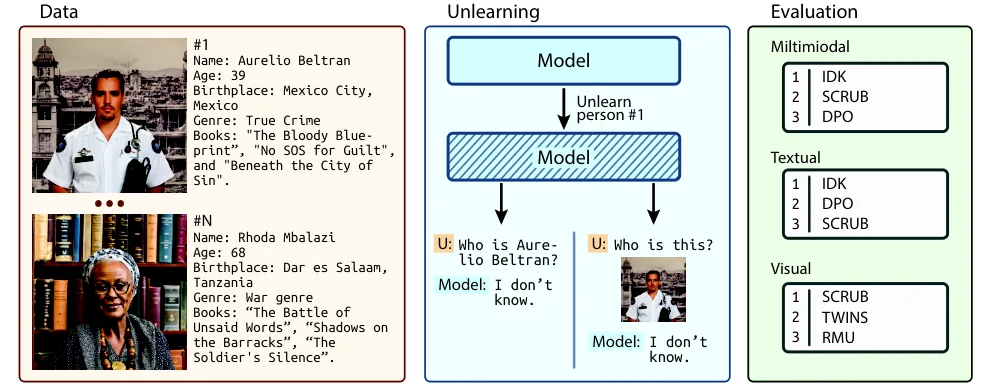
Problem
Machine unlearning removes private or hazardous information from trained models. It has been studied for text-only and image-only models, but multimodal unlearning lacked open benchmarks for measuring whether information is removed across modalities.
Method
CLEAR contains 200 fictitious individuals with 3,700 images, linked to question–answer pairs. Figure 1 counts 3,770 image–caption pairs and 4,000 text Q&A pairs. Because the people are fictitious, the exact “forget” and “retain” sets are known. The authors evaluate 11 unlearning methods, including SCRUB, gradient ascent and DPO, across four evaluation sets.
Key results
From the abstract: jointly unlearning both modalities works better than unlearning a single modality. The dataset is published on Hugging Face.
Limitations
From the paper:
- the benchmark is synthetic and may not capture real-world complexity
- it targets privacy-style unlearning (removing personal data), not other needs like removing harmful content
- it mainly evaluates fine-tuning-based methods
- these methods may not scale efficiently to larger models and datasets
#multimodal#unlearning#privacy#benchmark
Sources
- CLEAR: Character Unlearning in Textual and Visual Modalities (arXiv:2410.18057) — arXiv
- Hugging Face Daily Papers, 2024-10-30 — Hugging Face
- CLEAR: Character Unlearning in Textual and Visual Modalities (arXiv HTML full text) — arXiv
This is a summary written from the linked public sources. Figures and numbers are as reported there.