Paper summary: LLM-Microscope: Uncovering the Hidden Role of Punctuation in Context Memory of Transformers
Tokens we treat as filler (punctuation, articles, stop words) carry a surprising share of an LLM's contextual memory; removing them hurts MMLU and long-context scores, and the paper releases a toolkit to measure this.
Problem
How do LLMs keep track of context across a long input? Intuition says content words carry the meaning.
Method
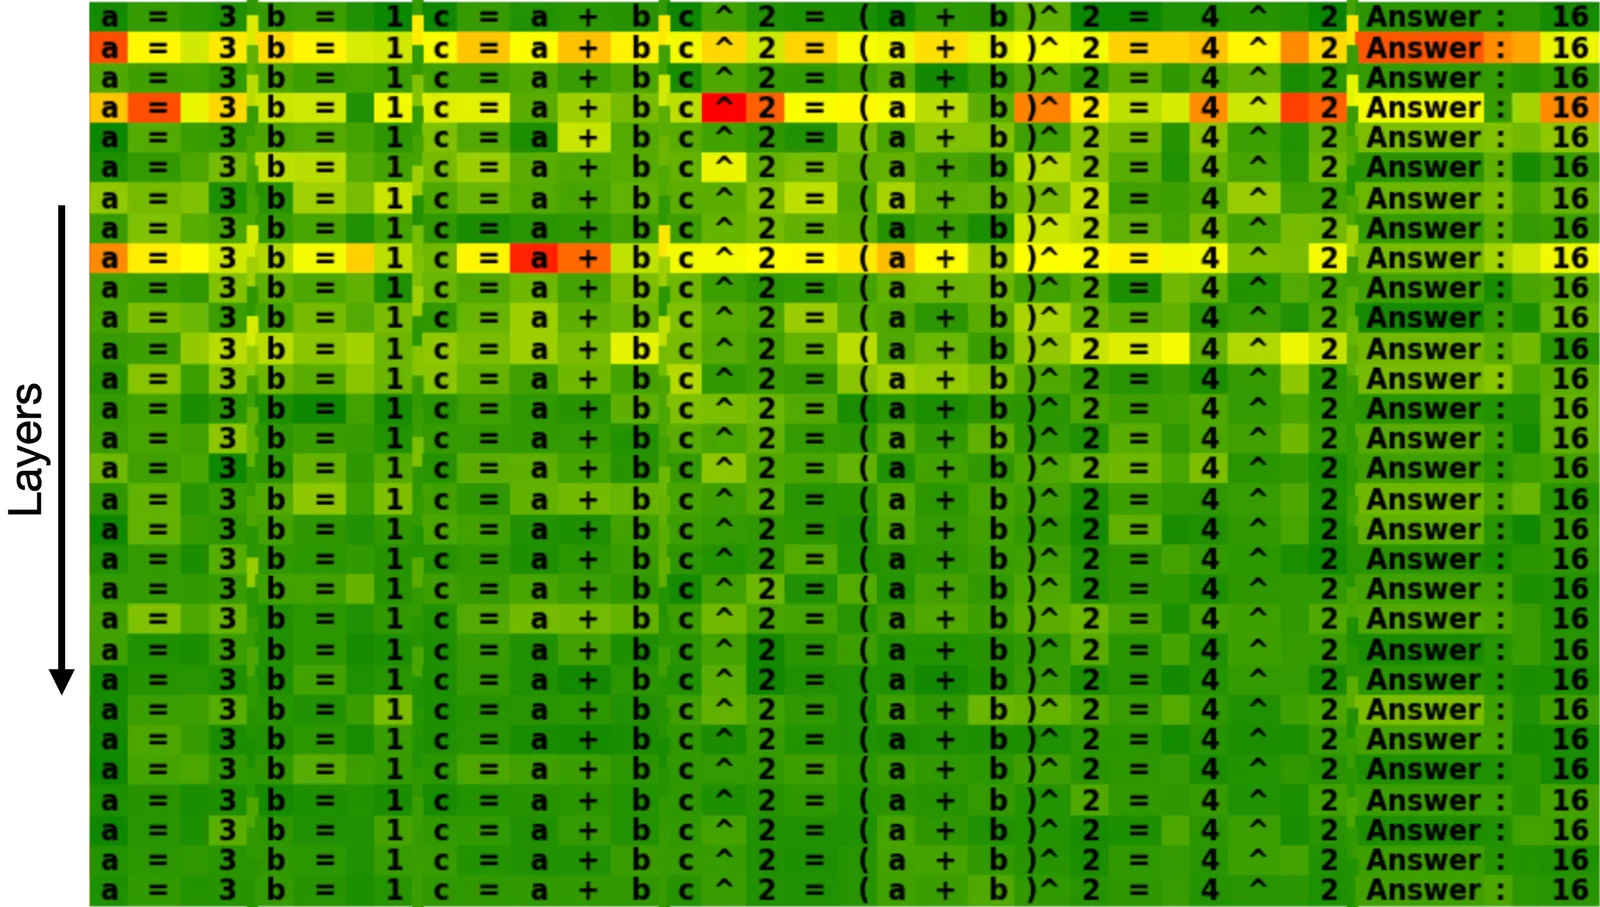
The authors introduce methods to measure how much contextual information each token’s representation holds, and how linear each layer-to-layer transformation is. They test by removing tokens and measuring the effect. LLM-Microscope is the released toolkit: token-level non-linearity, contextual memory, layer contributions (an adapted Logit Lens) and intrinsic dimensionality. Figure 1 shows a token-wise non-linearity visualisation for Llama3-8B.
Key results
From the abstract:
- “minor” tokens such as determiners and punctuation carry surprisingly high context
- removing them, especially stop words, articles and commas, consistently degrades performance on MMLU and BABILong-4k, even when only irrelevant tokens are removed
- there’s a strong correlation between contextualisation and linearity
Limitations
From the paper:
- applying a pretrained LM head to intermediate layers without fine-tuning may not reflect what those layers really do
- the adapter-based memory measure depends on the adapter’s design and training
- results may not generalise to all architectures, sizes or training setups
Sources
- LLM-Microscope: Uncovering the Hidden Role of Punctuation in Context Memory of Transformers (arXiv:2502.15007) — arXiv
- Hugging Face Daily Papers, 2025-02-24 — Hugging Face
- LLM-Microscope: Uncovering the Hidden Role of Punctuation in Context Memory of Transformers (arXiv HTML full text) — arXiv
This is a summary written from the linked public sources. Figures and numbers are as reported there.