Paper summary: Qwen2.5-Omni Technical Report
Qwen2.5-Omni takes text, images, audio and video as input and streams back both text and speech, using a Thinker (LLM) and a Talker (speech generator) that share hidden states.
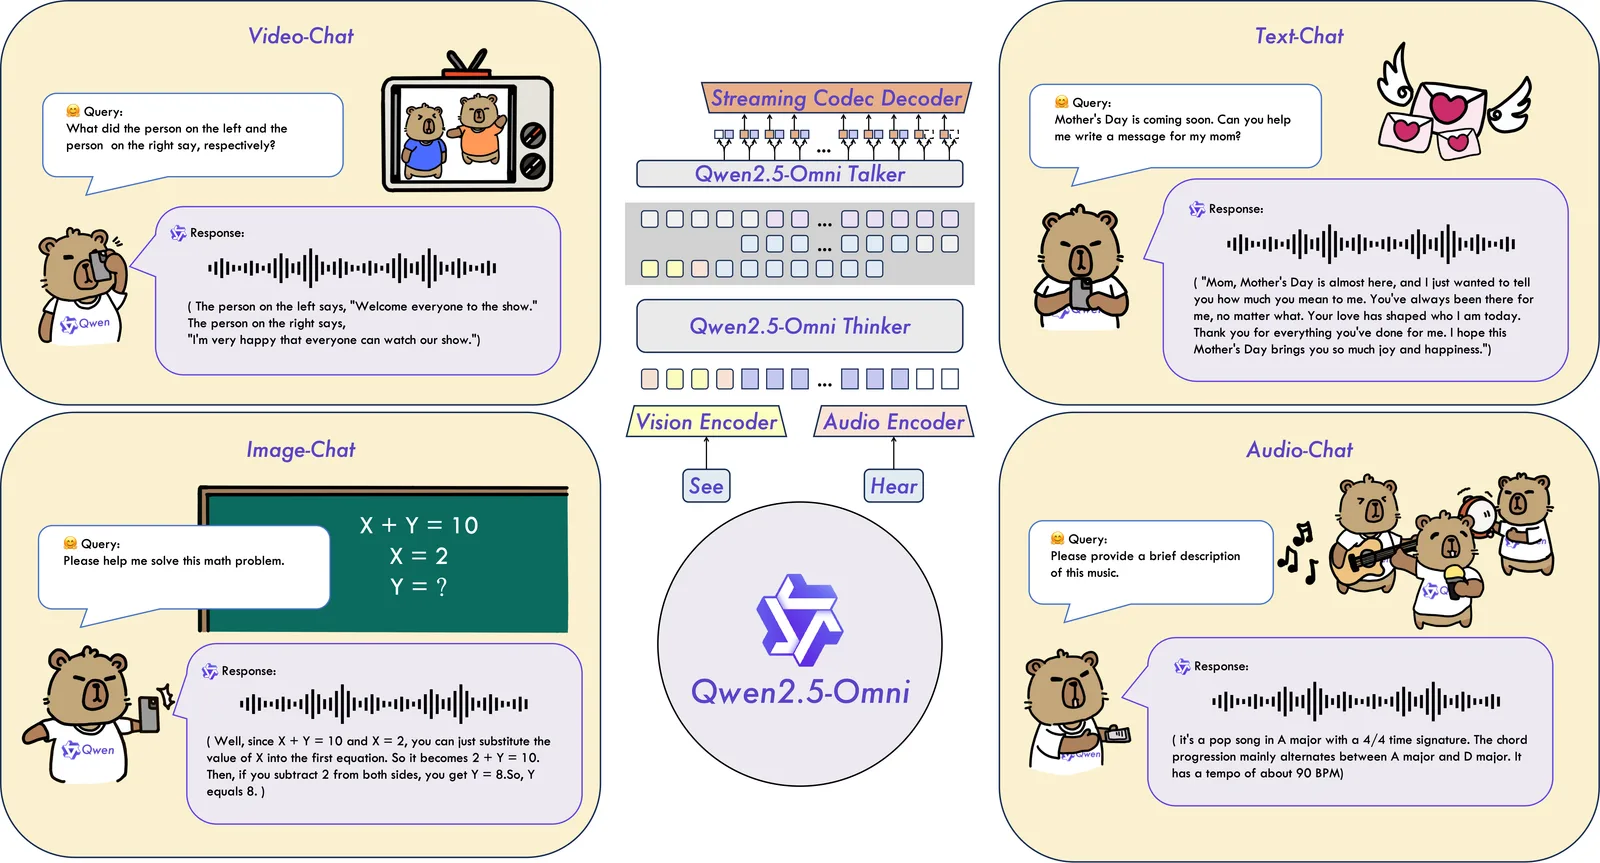
Problem
One model that can see, hear, read and speak in real time needs streaming inputs, synchronised audio and video, and generation of text and speech at once without the two interfering.
Method
- Block-wise audio and visual encoders, for streaming input.
- TMRoPE (Time-aligned Multimodal RoPE): audio and video are interleaved in time order with a new position embedding, so their timestamps line up.
- Thinker–Talker: the Thinker is an LLM that generates text. The Talker is a dual-track autoregressive model that reads the Thinker’s hidden states and produces audio tokens. Both are trained and run end to end.
- A sliding-window DiT decodes audio tokens in a streaming way to reduce the delay before audio starts.
Key results
From the abstract:
- comparable to similarly sized Qwen2.5-VL, and better than Qwen2-Audio
- state of the art on Omni-Bench
- speech-instruction following comparable to text input on MMLU and GSM8K
- the streaming Talker beats most streaming and non-streaming alternatives on robustness and naturalness
Limitations
There’s no dedicated limitations section in the extracted text. Results are the developers’ own.
Sources
- Qwen2.5-Omni Technical Report (arXiv:2503.20215) — arXiv
- Hugging Face Daily Papers, 2025-03-27 — Hugging Face
- Qwen2.5-Omni Technical Report (arXiv HTML full text) — arXiv
- Code repository (linked in the paper) — GitHub
This is a summary written from the linked public sources. Figures and numbers are as reported there.