Paper summary: GLM-4.5V and GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning
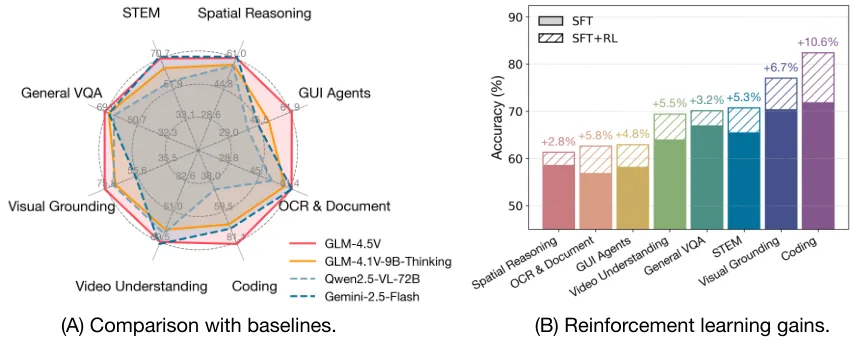
GLM-4.1V-Thinking and GLM-4.5V use a reasoning-centric training framework with Reinforcement Learning with Curriculum Sampling (RLCS); GLM-4.5V is reported to lead open models of its size on nearly all of 42 benchmarks.
Problem
How to train VLMs that reason across STEM, video, coding, grounding, GUI agents and long documents, not just describe images.
Method
A reasoning-centric training framework:
- large-scale pre-training of a capable vision foundation model, which the authors say “arguably sets the upper bound” for final performance
- Reinforcement Learning with Curriculum Sampling (RLCS), to unlock that potential across many task types
The models are a 9B dense model (GLM-4.1V-9B-Thinking) and a 106B-total / 12B-active MoE (GLM-4.5V). The report also mentions GLM-4.6V.
Key results
From the abstract:
- across 42 public benchmarks, GLM-4.5V is state of the art among open models of similar size on nearly all tasks, and competitive with or better than Gemini-2.5-Flash on coding and GUI agents
- the smaller GLM-4.1V-9B-Thinking beats the much larger Qwen2.5-VL-72B on 29 benchmarks
Limitations
From the paper: RL raises task completion rates but does not consistently improve reasoning quality. In some cases, correct answers come with flawed reasoning.
Sources
- GLM-4.5V and GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning (arXiv:2507.01006) — arXiv
- Hugging Face Daily Papers, 2025-07-02 — Hugging Face
- GLM-4.5V and GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning (arXiv HTML full text) — arXiv
This is a summary written from the linked public sources. Figures and numbers are as reported there.