Paper summary: GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models
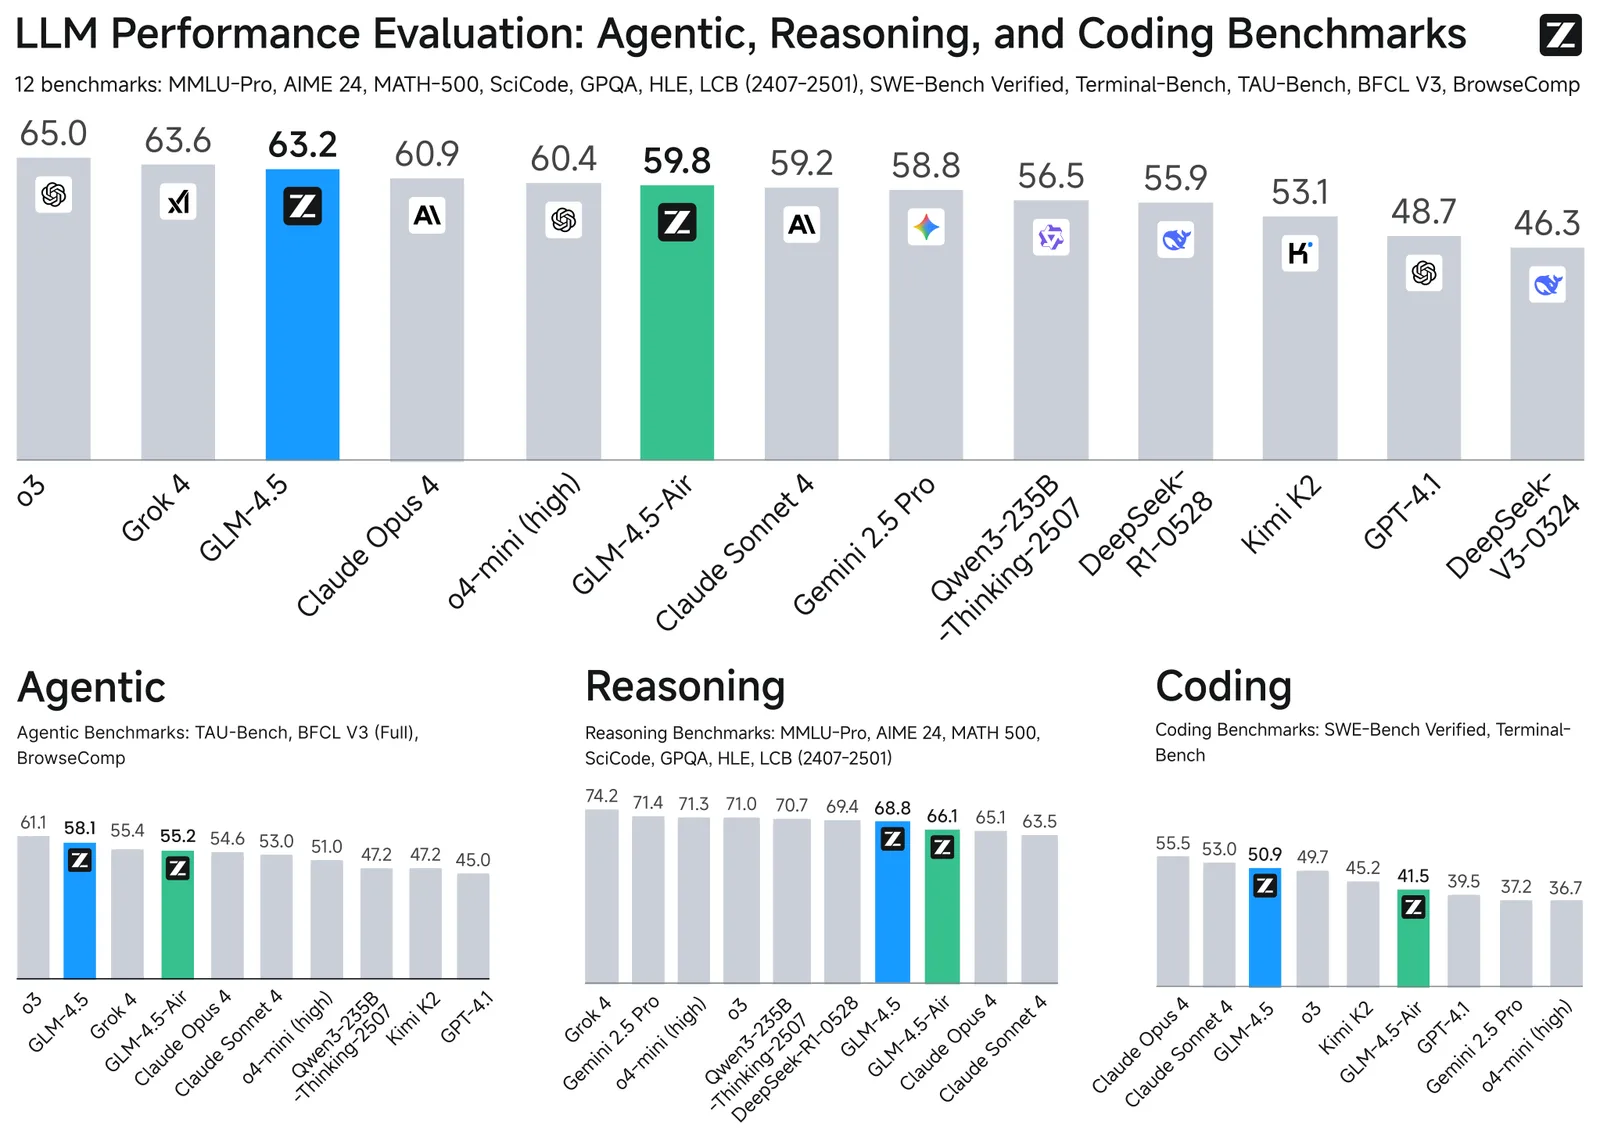
GLM-4.5 is an open MoE LLM (355B total, 32B active) with hybrid thinking and direct modes, trained on 23T tokens plus expert iteration and RL, reporting 70.1% TAU-Bench, 91.0% AIME 24 and 64.2% SWE-bench Verified.
Problem
Strong performance on agent tasks, reasoning and coding in one open model, at a manageable active size.
Method
GLM-4.5 is a Mixture-of-Experts model with 355B total and 32B activated parameters. It supports both thinking and direct-response modes. Training uses 23T tokens in multiple stages, then post-training with expert model iteration and reinforcement learning. A compact GLM-4.5-Air (106B) is released too.
Key results
From the abstract:
- 70.1% on TAU-Bench (agentic)
- 91.0% on AIME 24 (maths)
- 64.2% on SWE-bench Verified (coding)
- ranks 3rd overall among all evaluated models and 2nd on agentic benchmarks (Figure 1)
Limitations
There’s no dedicated limitations section in the extracted text. The ranking depends on which models and benchmarks the authors chose to compare.
Sources
- GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models (arXiv:2508.06471) — arXiv
- Hugging Face Daily Papers, 2025-08-11 — Hugging Face
- GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models (arXiv HTML full text) — arXiv
- Code repository (linked in the paper) — GitHub
This is a summary written from the linked public sources. Figures and numbers are as reported there.