Paper summary: QeRL: Beyond Efficiency -- Quantization-enhanced Reinforcement Learning for LLMs
QeRL combines NVFP4 quantisation with LoRA for RL training of LLMs; beyond saving memory and speeding up rollouts, quantisation noise raises policy entropy and helps exploration. It enables RL on a 32B model with one H100.
Problem
RL is key to LLM reasoning, but it’s expensive: lots of GPU memory and long rollout phases.
Method
QeRL pairs NVFP4 4-bit quantisation with LoRA (my QLoRA study post covers the basic idea of 4-bit base weights plus adapters). The authors’ further finding: quantisation noise increases policy entropy, which improves exploration during RL. Adaptive Quantization Noise (AQN) tunes that noise during training.
Key results
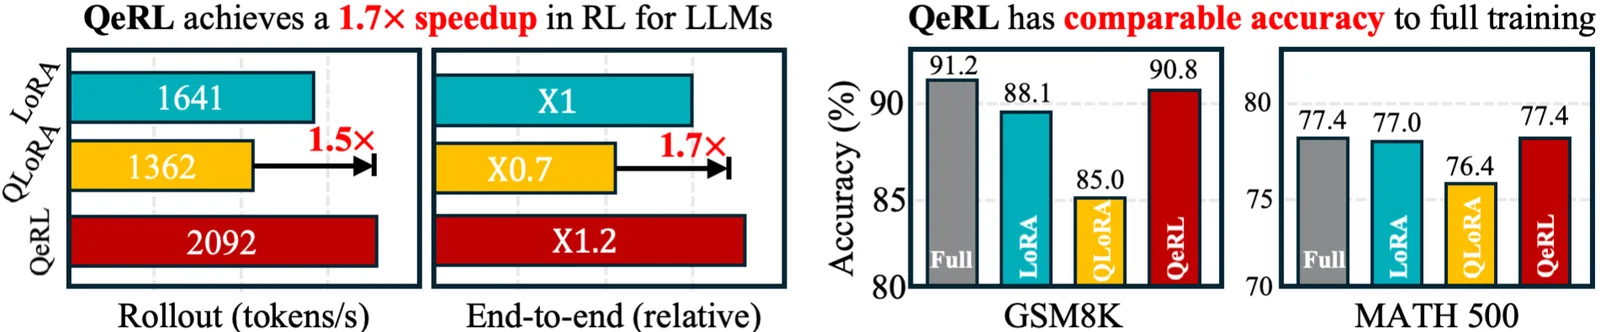
From the abstract and Figure 1:
- over 1.5× speed-up in the rollout phase
- the first framework to enable RL training of a 32B LLM on a single H100 80GB
- faster reward growth and higher final accuracy than 16-bit LoRA and QLoRA
- for the 7B model, matches full-parameter fine-tuning on GSM8K (90.8%) and MATH 500 (77.4%)
Limitations
From the paper: experiments cover 3B to 32B, so whether it holds above 70B is open. Because RL runs take tens to hundreds of hours, evaluation was limited to reasoning benchmarks.
#llm#rl#quantisation#efficiency
Sources
- QeRL: Beyond Efficiency -- Quantization-enhanced Reinforcement Learning for LLMs (arXiv:2510.11696) — arXiv
- Hugging Face Daily Papers, 2025-10-14 — Hugging Face
- QeRL: Beyond Efficiency -- Quantization-enhanced Reinforcement Learning for LLMs (arXiv HTML full text) — arXiv
- Code repository (linked in the paper) — GitHub
This is a summary written from the linked public sources. Figures and numbers are as reported there.