Paper summary: Can LLMs Clean Up Your Mess? A Survey of Application-Ready Data Preparation with LLMs
A survey of using LLMs to prepare application-ready data: cleaning, integration and enrichment, moving from rule-based pipelines to prompt-driven and agentic workflows.
Problem
Analytics, visualisation and decision-making need application-ready data. Traditional preparation relies on hand-crafted rules and domain-specific models, which take a lot of manual effort and expertise.
Method
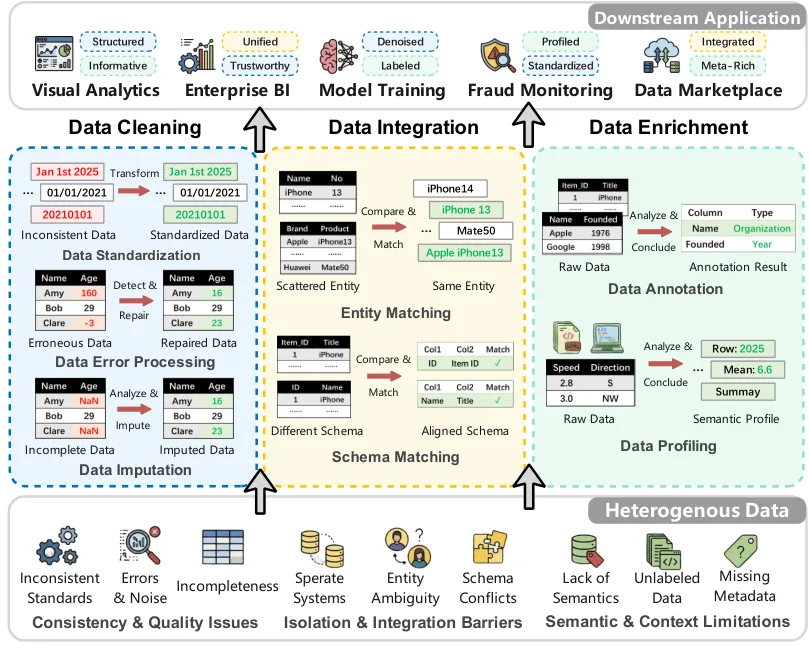
The survey reviews hundreds of works and organises LLM-based preparation into three tasks (Figure 1):
- data cleaning: standardisation, error processing, imputation
- data integration: entity matching, schema matching
- data enrichment: annotation, profiling
It describes the shift from rule-based, model-specific pipelines to prompt-driven, context-aware and agentic workflows.
Key results
For each task, the survey lists representative techniques with their strengths (e.g. better generalisation, semantic understanding) and their limitations. Its first limitations section explains why traditional methods are costly: heavy manual effort and dependence on expertise.
Limitations
As a survey, it maps a fast-moving area as of early 2026. A companion reading list is maintained on GitHub.
Sources
- Can LLMs Clean Up Your Mess? A Survey of Application-Ready Data Preparation with LLMs (arXiv:2601.17058) — arXiv
- Hugging Face Daily Papers, 2026-01-27 — Hugging Face
- Can LLMs Clean Up Your Mess? A Survey of Application-Ready Data Preparation with LLMs (arXiv HTML full text) — arXiv
- Code repository (linked in the paper) — GitHub
This is a summary written from the linked public sources. Figures and numbers are as reported there.