Paper summary: OmniCompass: A Holistic Benchmark for Omni-Modal Video Grounding and Understanding
OmniCompass is a manually annotated benchmark for video grounding and understanding, with a vision track and an audio-visual track (when, where and what); across 50 MLLMs, the best scores are only around 40%.
Problem
Video benchmarks each cover only part of what “understanding a video” means, so it’s hard to diagnose omni-modal models systematically.
Method
OmniCompass has two tracks:
- OmniCompass-VL: vision-language models, tasks needing visual evidence (820 videos, 2,460 instances, short to long)
- OmniCompass-AV: omni-modal models, tasks needing joint audio-visual evidence (240 narrative- and audio-rich videos, 720 instances)
Each track has temporal grounding (when), spatial grounding (where) and QA (what), across perception and reasoning categories. Every instance is evaluated with the target specified by text only and by text + image. All instances are manually annotated with multi-round checks.
Key results
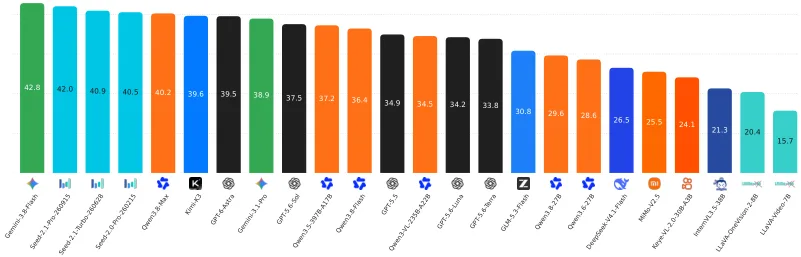
From the abstract and Figure 1: across 50 MLLMs, open-source models still lag proprietary ones. On OmniCompass-VL, the top scores are Gemini-3.8-Flash at 42.8% (proprietary) and Kimi-K3 at 39.6% (open; Kimi K3 is summarised here in July).
Limitations
There’s no dedicated limitations section in the extracted text. The audio-visual track is a smaller subset.
Sources
- OmniCompass: A Holistic Benchmark for Omni-Modal Video Grounding and Understanding (arXiv:2610.18829) — arXiv
- Hugging Face Daily Papers, 2026-10-16 — Hugging Face
- OmniCompass: A Holistic Benchmark for Omni-Modal Video Grounding and Understanding (arXiv HTML full text) — arXiv
- Code repository (linked in the paper) — GitHub
This is a summary written from the linked public sources. Figures and numbers are as reported there.