Paper summary: MVDream: Multi-view Diffusion for 3D Generation
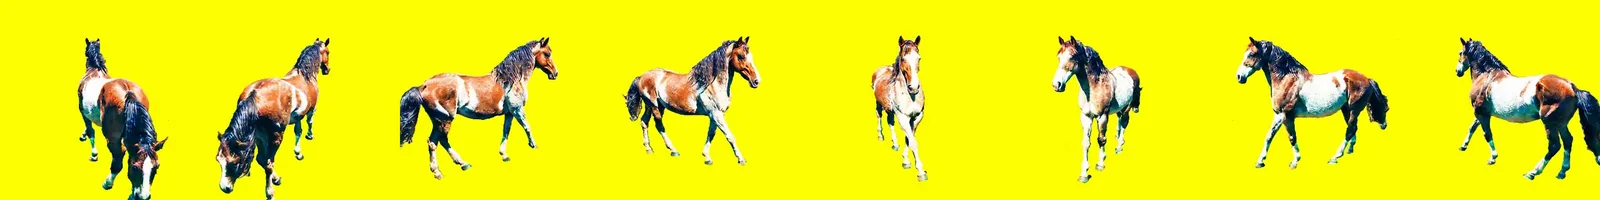
MVDream trains a diffusion model to generate several consistent views of an object at once, then uses it as a 3D prior for text-to-3D, which reduces problems like the "two-faced horse".
Problem
A popular route to text-to-3D is “2D lifting”: optimise a 3D representation so that renders of it look good to a 2D text-to-image diffusion model (Score Distillation Sampling). Because the 2D model judges each view independently, the results often have multi-view inconsistencies, like the multi-face “Janus” problem in the paper’s Figure 1, where a horse gets two faces.
Method
MVDream trains a multi-view diffusion model that generates several views of the same object (four orthogonal views in the main setup) jointly, from a text prompt. Training mixes 2D image–text data, for generality, with 3D data rendered from multiple angles, for consistency. The authors argue this model acts as a generalisable 3D prior that doesn’t care which 3D representation is used. They plug it into Score Distillation Sampling, and also show few-shot concept learning similar to DreamBooth.
Key results
The paper reports that using the multi-view model significantly improves the consistency and stability of existing 2D-lifting methods, and that it can learn new concepts from a few 2D examples for 3D generation.
Limitations
Their discussion notes that the main model is trained for four orthogonal views at the same elevation. A small extension experiment generalised to more, non-orthogonal views, but with worse quality than the orthogonal setting.
Sources
- MVDream: Multi-view Diffusion for 3D Generation (arXiv:2308.16512) — arXiv
- Hugging Face Daily Papers, 2023-09-01 — Hugging Face
- MVDream: Multi-view Diffusion for 3D Generation (arXiv HTML full text) — arXiv
This is a summary written from the linked public sources. Figures and numbers are as reported there.